The missing paragraph may be an image
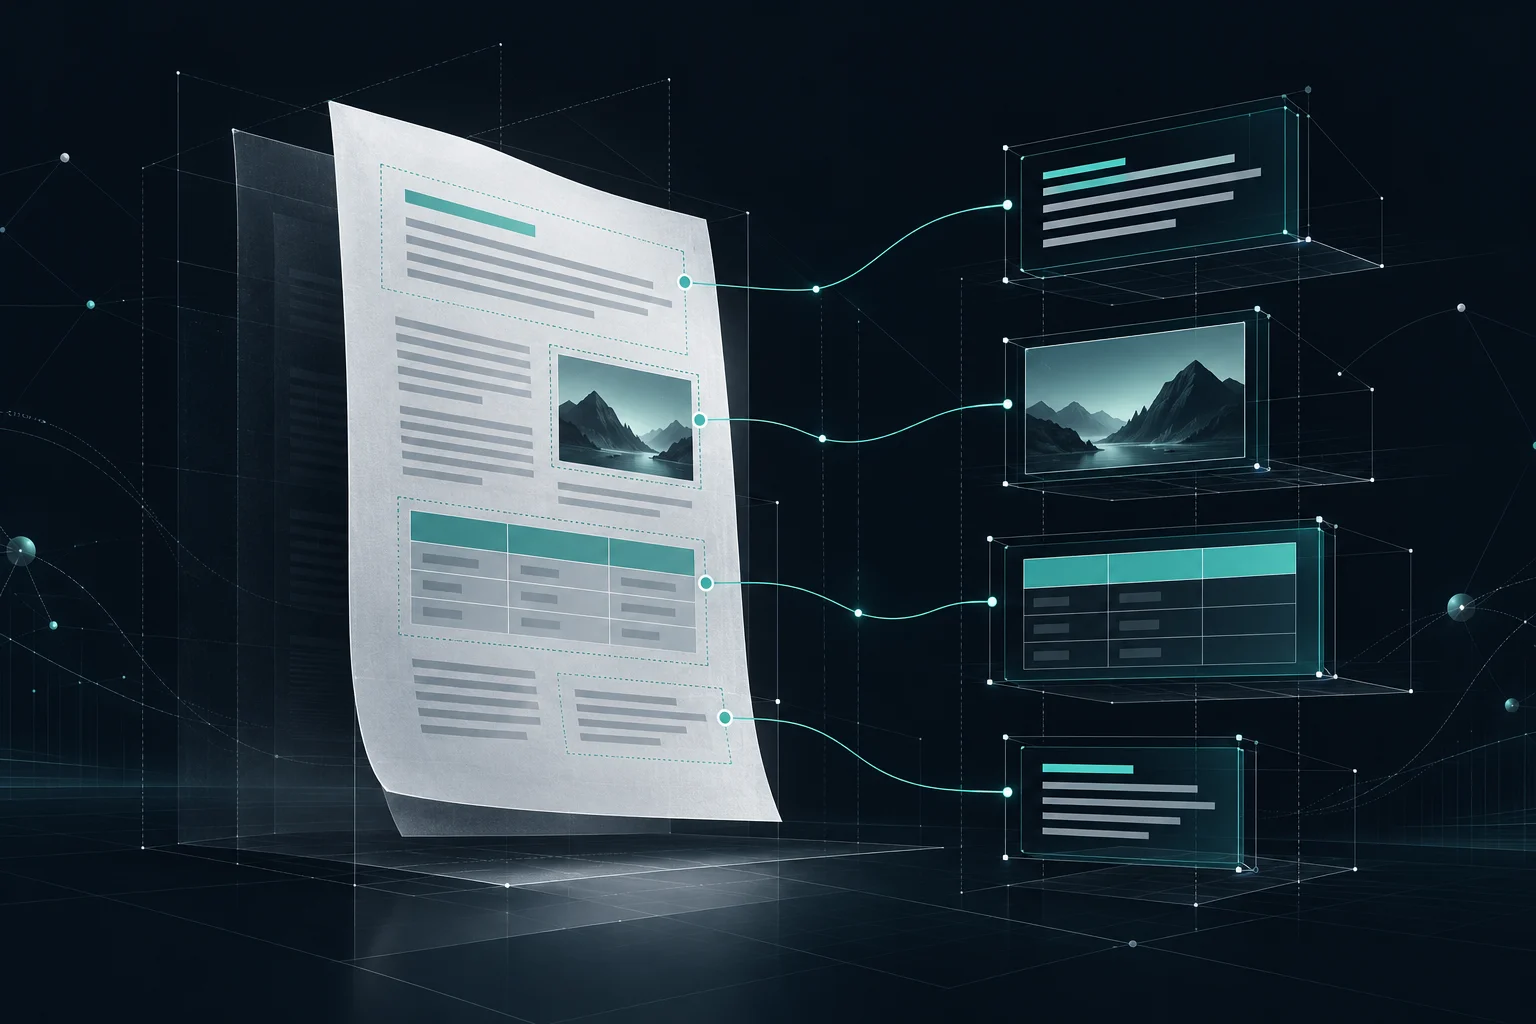
A DOCX can contain a scanned table, screenshot or diagram with important text. Extracting its ordinary paragraphs does not necessarily recover that content. Native picture OCR makes embedded image text part of document processing rather than relying on the document’s existing text alone.
Request processing and prove execution
The parse worker now requests native picture OCR for DOCX, with Nemotron-backed handling in Docling. Reporting distinguishes a requested preset from evidence that OCR actually ran. Incomplete or malformed batches are rejected rather than silently presented as complete.
Keep provenance attached
The accompanying changes retain the Bronze container path and correlate native picture OCR without changing existing text hashes. PDF OCR provenance is also restored to reflect proven execution. These details help connect extracted content to its source and explain what processing produced it.
Validate difficult documents
Use a DOCX with known text inside an embedded image, then compare the extracted output with that image and check the provenance record. OCR remains dependent on source quality, language and layout. Preview validation should include failed and partial documents as well as successful ones.